Splitters
What a Splitter does
A Splitter takes one file that contains several documents and breaks it into its separate parts. It reads every page, works out where one document ends and the next begins, classifies each segment against the document types you described, and sends each part onward on its own.
The common case is a scanner or a supplier that emails one PDF holding an invoice, a packing slip and a signed delivery note. Extracting that as a single document produces nonsense. A Splitter turns it into three documents that each reach the right flow. Splitters also accept spreadsheets, where each sheet becomes its own document.
A Collection answers “which flow does this document belong to?”. A Splitter answers “how many documents are in this file, and where does each one go?”. Use a Collection when each file holds one document of unknown type; use a Splitter when one file holds several.
How segmentation works
Every page is examined in order and assigned to exactly one segment. Segments never overlap and never leave a gap, so every page of the input ends up somewhere: there is no silent page loss.
The rules Tavnit applies when deciding where a document ends:
| Situation | What happens |
|---|---|
| Headers and logos repeat on every page | Not treated as a new document. A repeated letterhead across a five-page invoice is still one invoice. |
| The title, issuer, party, document number, format or date changes | Treated as a real boundary: a new segment starts. |
| Attachments, photos, quotes and screenshots | Always their own segment, even when they sit immediately before or after a matched document. |
| A segment matches none of your document types | Still produced, listed under Other Documents. It is never merged into a neighbour just to avoid an unmatched result. |
There is no confidence score. A segment either matches one document type or it matches none: the classifier is instructed to answer “no match” rather than guess. Unmatched segments are where you should look first when a split does not do what you expected.
Create a Splitter
A Splitter is a list of document types. Each one has a title, a description of what it looks like, and an optional destination. There are no rules to write: the description is what the classifier matches against.
- 1Open Splitters, click Create Splitter and enter a Splitter Name for the bundle it receives, such as Supplier delivery packets rather than Splitter 2.
- 2Click Add Document Type for each kind of document in the bundle, with a title and a description of what appears on the page. At least one type is required. Or click Suggest with AI (below) to draft them from a sample.
- 3Under Output automation, choose a destination for each type (see the table below).
- 4Click Split and upload a bundle, or send one to the Splitter's email address.
- 5Open the completed split in Split History and check each document's page range and match.
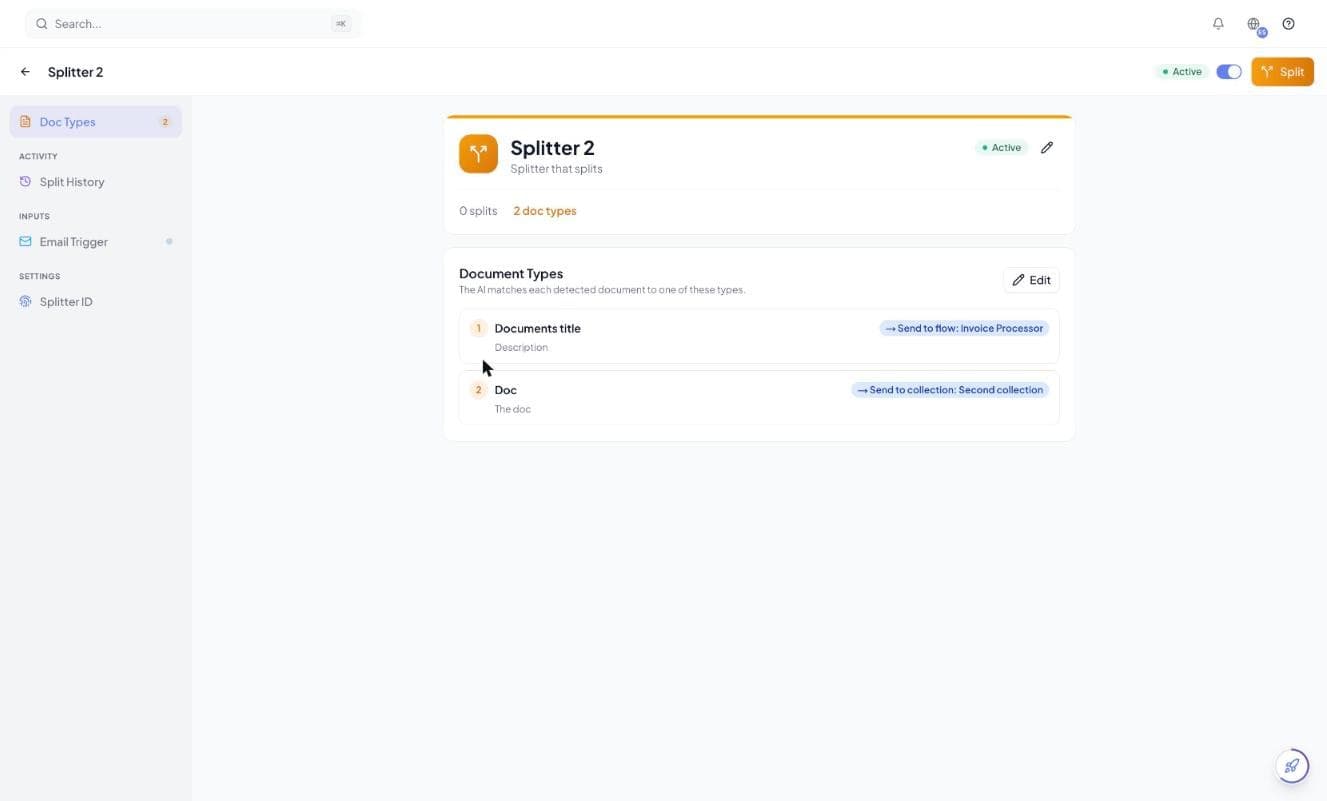
The description is the only thing distinguishing one document type from another. Write what a person would look at to tell them apart, and say what it is not: “packing slip: lists quantities with no prices, signature box at the foot. NOT the invoice” beats “packing slip”.
Let the AI suggest document types
If you have a real bundle to hand, the assistant can draft the document types for you. It reads a sample, proposes one type per distinct document it finds, and writes descriptions meant to tell them apart.
- 1While creating the Splitter, click Suggest with AI next to Document Types.
- 2Optionally describe what kinds of bundles the Splitter will receive. It helps the assistant name the types the way your team does.
- 3Upload a sample bundle: a PDF that mixes several documents, up to 25 pages.
- 4Review the proposals. Each shows the pages it was found on; untick the ones you do not want (pages marked Not a document type are left out) and edit titles and descriptions inline.
- 5Click Add N documents (N is how many you kept) to append them to the Splitter, then set their destinations.
Analysing the sample does not run a split. Nothing is saved until you create the Splitter.
Where each document goes
Destinations are set per document type, not per Splitter. That is what lets one bundle fan out: invoices to an extraction flow, delivery notes to a Collection, everything else emailed to a person.
| Output automation | What happens to the segment |
|---|---|
| Send to flow | A normal extraction run is created for that segment, tagged with the split and document type it came from. |
| Send to collection | The segment is classified again by the Collection and routed to whichever flow matches. |
| Send by email | The segment is emailed as an attachment (a PDF, or a single-sheet spreadsheet for workbooks) to the one address you enter. |
| None | The segment is kept in the split result, ready to download, but not sent anywhere. |
Segments that match no document type are never dispatched. They stay in the split result under Other Documents, where you can download them.
A Splitter can feed a Collection, and a Collection can route to a Splitter. In the Collection picker, any Collection that routes back to this Splitter is disabled and labelled routes to this splitter, and at run time a segment is never sent into a Collection that would return it to the same Splitter, so a mis-set pair cannot spin documents in a circle.
Runs created from a segment carry their origin with them. The webhook payload for such a run includes the split it came from and the document type it matched, so you can trace a row back to the original bundle. See webhook payloads.
When a Splitter runs inside a Pipeline, the pipeline's connections decide where each document type goes, and the Splitter's own output automation does not fire, so nothing is sent twice.
Splitting spreadsheets
In a workbook, the sheets are the boundaries. Every visible, non-empty sheet becomes its own document; the AI only decides which document type each sheet is.
- Accepted formats:
.xlsx,.xlsand.csv. A CSV is a single sheet. - Hidden and empty sheets are ignored. A workbook with no visible, non-empty sheet is rejected.
- Each sheet is sent onward as a single-sheet spreadsheet, so the flow that receives it gets real spreadsheet input.
- In the split result, the page range of a sheet reads as its position in the workbook.
- Very large sheets are rejected with an error.
Sending files to a Splitter
A Splitter accepts files three ways: uploaded in the app, posted to the API, or emailed to its own address. Every file becomes its own split.
| Route | How it works |
|---|---|
| Upload in the app | Click Split, pick the Splitter in Split Document and drop one or more PDFs or spreadsheets. Each file starts its own split. |
| API | Post the file with the Splitter ID to /splits/run. The API also accepts images. Copy the ID from the Splitter ID panel; see the API page. |
| Open the Email Trigger panel, switch it on and forward bundles to the Inbox Address. Each PDF, image or spreadsheet attachment becomes its own split. Use Allowed Senders to restrict who can send. |
Accepted attachment types, the reasons a file may be skipped and duplicate protection are the same as everywhere else. See email integration. If the trigger is switched off, the mail is accepted and discarded without a bounce.
Reading a split result
Open a split from Split History to see what the Splitter decided. The split is processing until the banner shows it as completed or failed; a failed split shows the error.
- Pages and Docs Found for the whole file
- Where the file came from, and the sender when it arrived by email
- Detected Documents: each segment that matched a type, with its page range, its destination and its delivery status
- Other Documents: segments that matched nothing, the first place to look when a split goes wrong
- View Run on any segment sent to a flow, and Download on every segment
Wrong boundaries usually mean two document types are described too similarly. Wrong matches usually mean a description is too vague. In both cases the fix is in the document type descriptions, not in the file.
Getting the original file back
Tavnit keeps the bundle exactly as it was uploaded. Download it from the Original File link in Split Details, or fetch it over the API by split ID.
curl "https://run.tavnit.io/api/splits/<split_id>/source-file" \
  -H "X-API-Key: tvnt_your_key_here"

# Or stream the file itself
curl "https://run.tavnit.io/api/splits/<split_id>/source-file?download=true" \
  -H "X-API-Key: tvnt_your_key_here" -OJ
The default response is JSON with a signed, time-limited url (7 days unless you pass a shorter expires_in in seconds); download=true returns the file itself. This returns the whole bundle, not the segments: each segment sent to a flow is a run of its own, with its own source file.